Solnix Media · Research & Insights
The Frontier
Intelligence
Product notes from Solnix and research on enterprise AI, with every figure linked to its source: studies, regulators and the companies that published them.
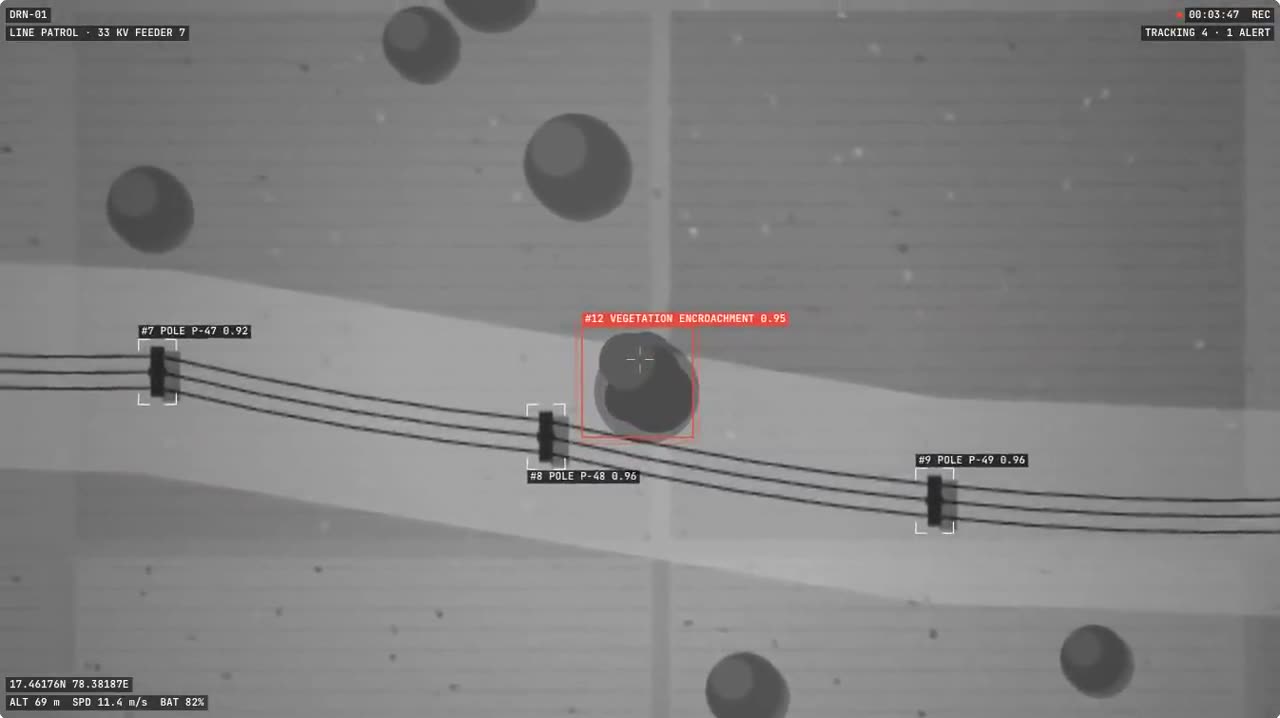
Drone ops: track every object in the frame, flag only what matters
Live aerial feeds that detect and follow many objects at once, keep an ID on each, and turn the few that break a rule into checks for your team.
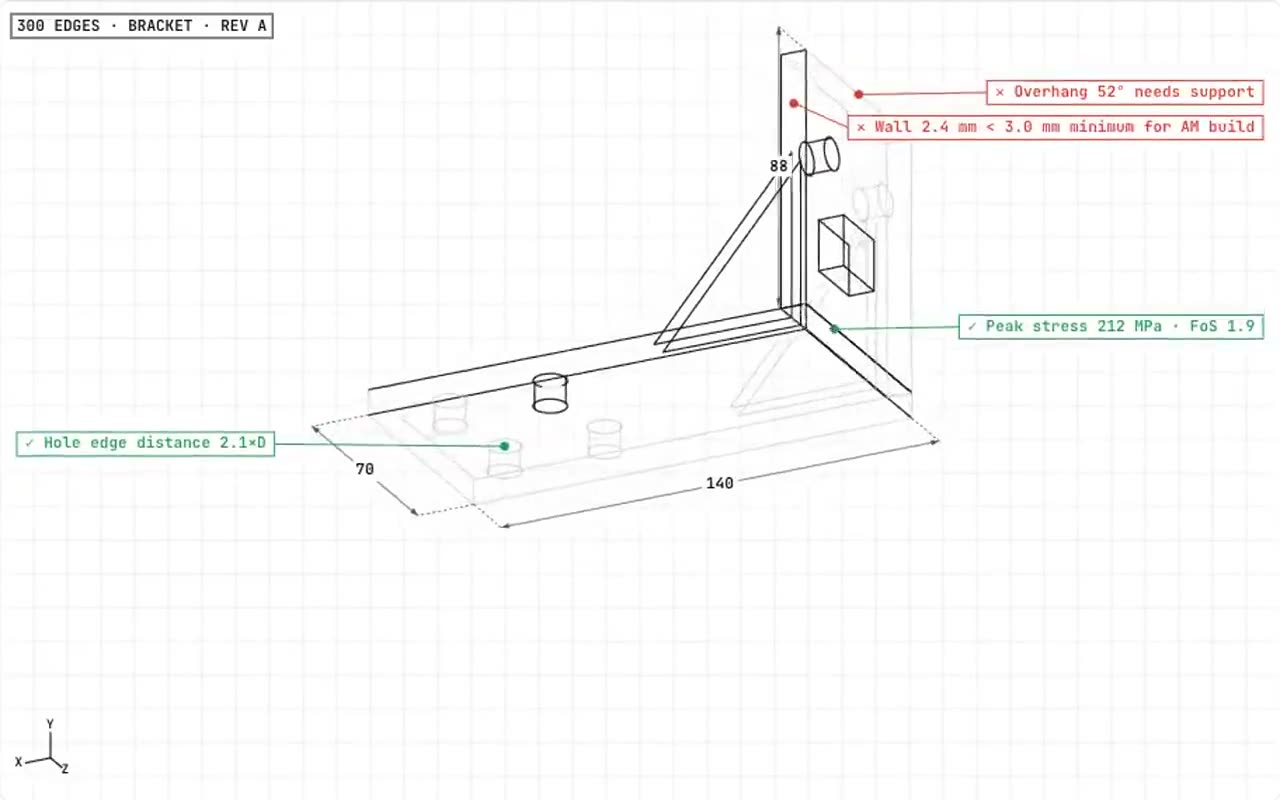
AI CAD: from a plain-language brief to a checked, dimensioned design
Describe a part or structure in a sentence. A design agent generates the geometry and variants, checking agents test it, and an engineer signs off.
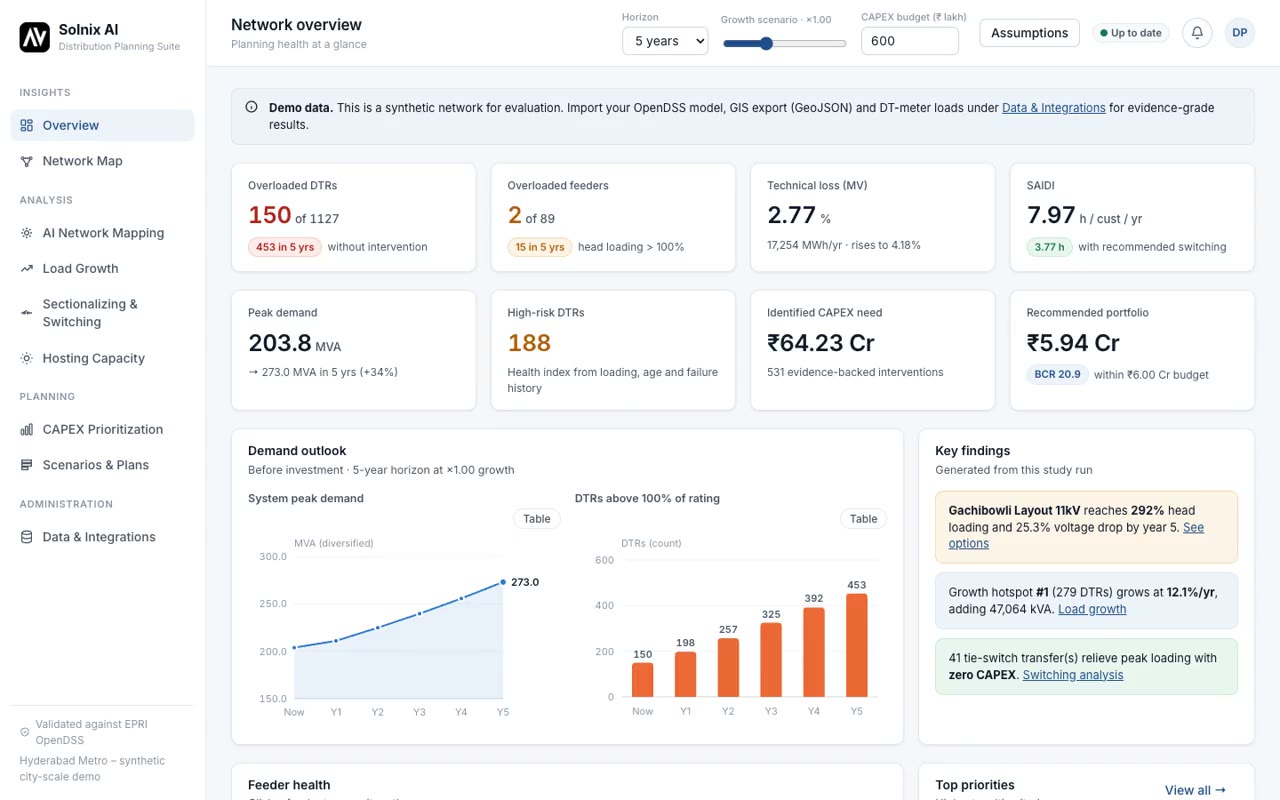
AI Feeder: planning distribution capex with load flow you can check
Network mapping, load-growth forecasting, switching, hosting capacity and a budget-constrained capex plan, with load flow cross-checked against OpenDSS.
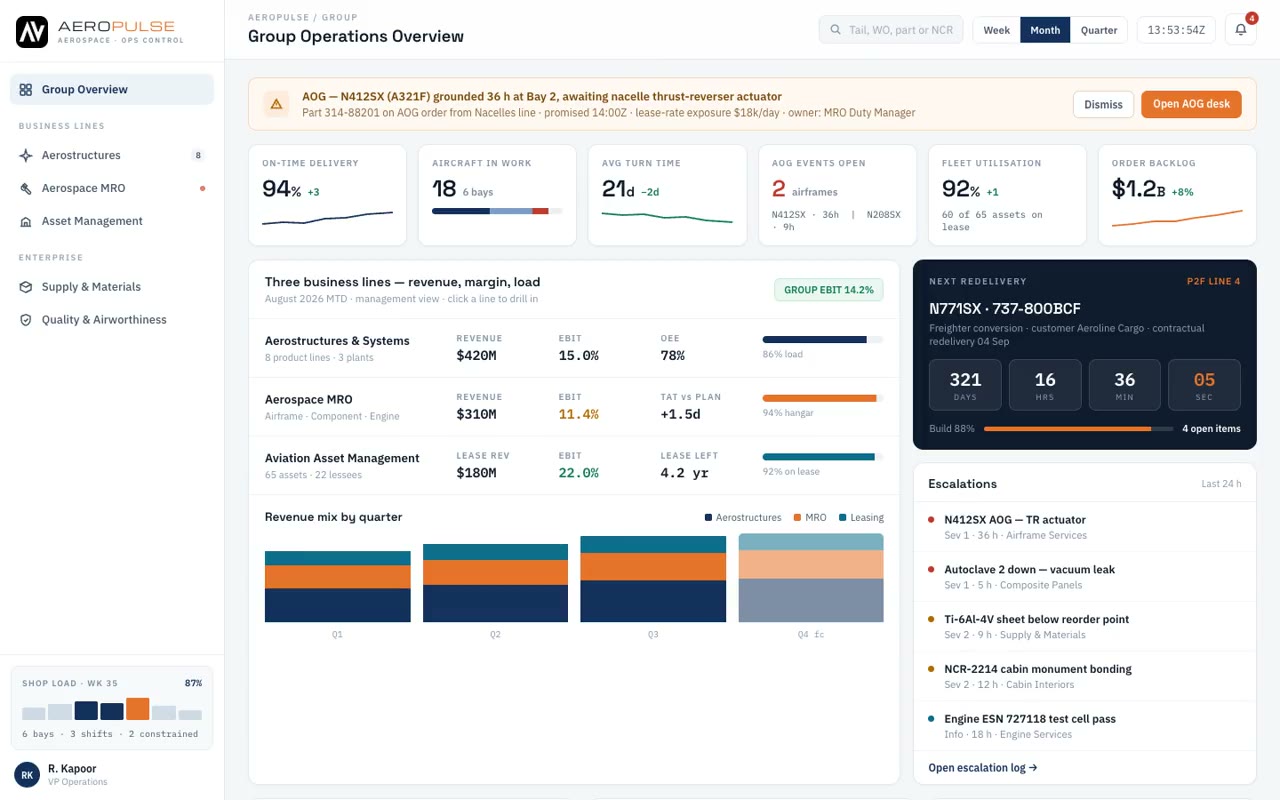
AeroPulse: one operations view across aerostructures, MRO and leasing
A group operations dashboard for an aerospace business with three lines: the AOG that matters now, the next redelivery and what is escalating.
How small and mid-sized businesses are growing with AI: what the 2025 data shows
58% of US small businesses now use generative AI, and AI-using small businesses report hiring. But only a small group of companies see AI move their profit line. Here is what separates them.
Does AI make teams more productive? What controlled studies actually measured
In a study of 5,179 support agents, an AI assistant lifted issues resolved per hour by 14%, and by 34% for newer agents. A study of 758 consultants shows the other side: outside its strengths, AI made work worse.
Speed to lead: the first hour decides what your ad spend returns, and AI can cover it
Companies that responded to a web lead within an hour were nearly 7 times as likely to qualify it as those that waited even one hour longer. Most companies don't come close.
Agents inside the process: where multi-agent orchestration beats BPM, and where it doesn't
BPM is good at the happy path. Agents are good at the messy middle. The architecture that works keeps both, with durable state and a person at the decisions that matter.
Beyond naive RAG: the retrieval techniques that hold up in production
Fixed chunks and cosine similarity fail on real document sets. Hybrid retrieval, contextual chunks, reranking and an evaluation set are what move accuracy.
Prior authorization in 2026: what the CMS rule changes and where automation actually helps
Payers now face hard decision deadlines and must expose a prior authorization API. Here is where AI helps on the provider and payer side, and where a clinician must still decide.
Choosing an LLM for the enterprise: an evaluation you run on your own work
Public leaderboards tell you which model is generally strong. Only an evaluation on your own tasks, data and constraints tells you which one to deploy.
Alternative data: the backtest is the easy part
Most alternative data signals that look good in a backtest are overfit, and the ones that are real carry compliance risk. A due-diligence checklist for both.
Model drift in production: how to detect it, and what to do when you find it
Data changes, the world changes and hosted models change underneath you. Monitoring inputs, outputs and outcomes, with a plan for each, is what keeps a model trustworthy.
Faster OODA loops with AI, and where human judgement stays in the loop
AI shortens the observe and orient steps by fusing sensor data. Policy requires that decide stays with people. How to design systems that respect both.
Catching defects on the line with vision AI: what works with few defect images
Defects are rare, so supervised models starve. Anomaly detection trained on good parts, tied to takt time and the quality system, is the practical route.
Predictive maintenance on the distribution grid: from asset health to the capex plan
Transformer gas analysis, load growth, vegetation and reliability indices each predict failures. Combined, they decide which assets to replace first.
AI claims triage: what to automate, what to route, and what regulators now expect
Triage, document reading and fraud flags are good uses of AI in claims. State regulators now expect written governance for each of them.
AI in due diligence: reading the data room without missing what matters
Language models can read every contract in a data room. The work is making sure every finding is cited, checked and in front of the deal team in time.
AI tutors: what the controlled trials show, including when they hurt learning
A Harvard trial found students learned more with a well-designed AI tutor. A high-school trial found unrestricted ChatGPT lowered exam scores. The design is the difference.
Real estate underwriting with AI: climate risk, valuation models and the new rules
Property-level flood and climate data have changed what underwriting can see. New US rules set quality standards for automated valuation models.
Demand sensing vs demand forecasting: what the M5 competition taught CPG planners
The largest public retail forecasting competition was won by gradient-boosted trees using many short-term signals. What that means for a CPG planning team.
AI-assisted code review: what Google, Meta and GitHub have published, and a study that disagrees
Google applies ML-suggested edits to review comments; Meta ships LLM-written tests. A randomised study found experienced developers were slower with AI. How to read the evidence.
Government AI that lasts: what Robodebt and the Dutch benefits scandal teach
Two automated systems wrongly pursued hundreds of thousands of citizens and brought down a government. The safeguards they lacked are now in public-sector AI guidance.
Intraday risk: moving from end-of-day VaR to continuous exposure monitoring
FRTB replaced VaR with expected shortfall, BCBS 239 demands timely risk data, and Archegos showed what concentrated exposure can do in days.
Sepsis prediction: why one widely used model missed two-thirds of cases and another cut deaths
An external validation of the Epic Sepsis Model found it missed 67% of cases. A prospective study of TREWS linked timely response to lower mortality. What separates them.
AI guardrails in production: an engineering guide mapped to OWASP and NIST
Prompt injection, data leakage and confident wrong answers are the incidents that reach the news. Layered controls, mapped to published frameworks, are how you prevent them.
Retail's AI rebuild: why connected agents beat point solutions on returns and service
Returns cost US retailers $890 billion in 2024. A return touches support, inventory, finance and logistics, which is why one connected workflow beats four separate tools.
Follow on X
Get insights as they drop.
We post the key findings from every research piece on X — numbers, frameworks, and field notes, distilled to what matters.